Physical Address
Metro Manila, Philippines
Physical Address
Metro Manila, Philippines
A DNS steering system may begin with a simple job.
Receive a DNS query.
Look at a few signals.
Choose an eligible destination.
Return an answer.
As more features are added, the system may start keeping information about health checks, routing policies, network prefixes, ASN mappings, resolver classifications, ECS prefixes, recent decisions, counters, and temporary lookup results.
That state can become useful.
It can also become dangerous.
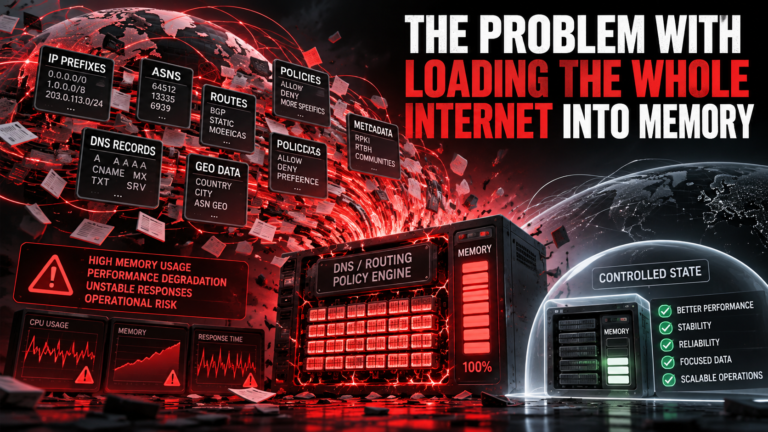
If runtime state grows without a clear limit, authoritative DNS behavior becomes harder to predict. Memory use can increase with traffic. Policy updates can become more expensive. Cleanup work can consume CPU time. A sudden increase in unique prefixes, resolvers, or query patterns can create work far beyond what operators expected.
For an authoritative DNS service, that is a serious problem.
The service should remain predictable even when traffic patterns are unusual.
This leads to an important engineering principle:
Runtime state should have clear limits on size, lifetime, scope, memory use, and update cost.
The word bounded does not mean that the state must be small.
It means operators should be able to answer questions such as:
How many entries can exist?

How much memory can they consume?

How long can they live?

Who can create them?

What causes an update?

How much work does an update require?

What happens when the limit is reached?
If these questions have no clear answers, the runtime state is not under control.
Consider an authoritative DNS service for:
www.example.comThe service can return three possible destinations:
Site A
192.0.2.10

Site B
198.51.100.10

Site C
203.0.113.10
A simple steering process might look like this:
DNS Query
    |
    v
Read policy
    |
    v
Check health
    |
    v
Choose destination
    |
    v
Return answer
The runtime state is small.
Now suppose the service gains additional capabilities:
DNS Query
    |
    +--> ECS prefix
    |
    +--> Resolver classification
    |
    +--> Country lookup
    |
    +--> ASN lookup
    |
    +--> Prefix policy
    |
    +--> Health information
    |
    +--> Weighted selection
    |
    +--> Statistics
    |
    +--> Recent lookup cache
    |
    v
DNS Answer
Every additional feature may introduce state.
For example:
Health table
Resolver table
Prefix table
ASN table
Country cache
ECS-related cache
Policy snapshot
Counters
Temporary query context
None of these is automatically bad.
The problem appears when their growth depends directly on uncontrolled input.
For example:
One new source prefix
        |
        v
Create state

Another new source prefix
        |
        v
Create more state

10,000 new prefixes
        |
        v
Create 10,000 entries

1,000,000 new prefixes
        |
        v
Create 1,000,000 entries?
If there is no limit, traffic can determine memory consumption.
That is a dangerous property for infrastructure that should answer DNS queries consistently.
Bounded runtime state means the implementation has defined limits.
A simplified example:
Policy snapshots       <= 2 generations
Health entries         <= configured destinations
Resolver cache         <= 50,000 entries
Prefix lookup cache    <= 100,000 entries
Entry lifetime         <= defined TTL
Temporary query state  <= query lifetime
The exact numbers are examples.
The important part is that limits exist.
A bounded system allows operators to reason about its worst case.
For example:
Maximum resolver entries:
50,000

Approximate bytes per entry:
256 bytes

Estimated maximum:
50,000 x 256
= 12,800,000 bytes
≈ 12.2 MiB
Real memory use may be higher because programming-language objects, indexes, allocator overhead, and metadata add cost.
But the operator can still estimate the order of magnitude.
Compare this with:
Resolver entries:
one per resolver seen

Maximum:
unknown
That second design is much harder to reason about.
It helps to separate three kinds of information.
Configuration describes what the operator wants.
Examples:
example.com policy
Site A weight = 60
Site B weight = 40
Country PH -> Site A
ASN rule -> Site B
Configuration might live in a database, file, API, or another management system.
Runtime state changes while the service is operating.
Examples:
Current health status
Active policy snapshot
Cached resolver classification
Recent prefix lookup
Counters
Temporary health timestamps
This state may exist only in memory.
Query-local state exists only while one query is being processed.
For example:
Query name
Query type
Resolver address
ECS prefix
Matched policy
Eligible destinations
Selected answer
Conceptually:
Query arrives
     |
     v
Create query context
     |
     v
Process decision
     |
     v
Send response
     |
     v
Discard query context
Query-local state is naturally bounded by the number of concurrent queries, assuming each query has a controlled memory cost.
The bigger risk usually comes from information retained after the query finishes.
Authoritative DNS sits in a critical part of the connection process.
Before a client can connect to:
www.example.comit often needs an address.
A simplified path is:
Application
    |
    v
Recursive Resolver
    |
    v
Authoritative DNS
    |
    v
Address returned
    |
    v
Application connection
RFC 1034 defines the basic DNS concepts involving resolvers, authoritative servers, caching, zones, and resource records. RFC 1035 defines the DNS message and implementation model.
A steering system extends the decision process behind an authoritative answer.
That extra logic should not make query cost unpredictable.
A desirable property is:
Normal query:
small predictable work

Unusual query:
small predictable work

Unknown resolver:
small predictable work

Missing ECS:
small predictable work

No policy match:
small predictable work
The answer may differ.
The amount of work should remain within known limits.
The first dimension is the number of retained objects.
Imagine a resolver-classification cache.
A naive implementation might behave like this:
Resolver seen?
    |
    +-- yes --> use cached classification
    |
    +-- no --> classify resolver
                |
                v
            store forever
That final step is the problem.
If the server encounters many unique addresses, the table continually grows.
Day 1       10,000 entries
Day 7       80,000 entries
Day 30     400,000 entries
Day 180  2,000,000 entries
Even if each object is small, accumulated state becomes significant.
A bounded approach might instead specify:
Maximum entries: 50,000

If full:
expire old entries
or
replace entries according to a defined policy
or
skip caching new classifications
Now growth has a ceiling.
Limiting entry count is only one part of the problem.
Runtime information should also have a defined lifetime.
Consider an ASN lookup result:
198.51.100.0/24 -> ASN XIf cached forever, the information may eventually become stale.
Networks change.
Prefixes can move between autonomous systems.
Routing announcements change.
A better model is:
Lookup result
     |
     v
Store temporarily
     |
     v
Expiration time
     |
     v
Refresh or discard
For example:
created_at = 12:00
valid_until = 13:00
At 13:00, the state is no longer treated as permanently valid.
The exact lifetime depends on the information and system design.
The key requirement is that temporary runtime state should not silently become permanent state.
Another important question is:
What causes a unique state entry to exist?
Consider ECS.
RFC 7871 defines the EDNS Client Subnet option, which can carry a network prefix associated with the originating client and allows authoritative systems to tailor answers based on network information. It also defines scope information relevant to caching tailored responses.
Suppose a steering system creates runtime state for every observed ECS prefix.
Conceptually:
ECS 198.51.100.0/24
        |
        v
Create entry

ECS 198.51.101.0/24
        |
        v
Create entry

ECS 198.51.102.0/24
        |
        v
Create entry
Now imagine thousands of prefixes.
A dangerous relationship appears:
Unique external inputs
        =
Unique retained state
That relationship should be treated carefully.
A safer design may use:
Preloaded prefix structures
Bounded classification cache
Aggregated network classifications
Fixed policy tables
Short-lived query context
instead of retaining indefinite state for every network ever observed.
Without ECS, the authoritative server usually sees the recursive resolver as the source of the query.
With ECS, additional network information may be available.
That can improve steering decisions.
But greater specificity can also create more possible classifications.
Consider:
Without ECS:

Resolver A
Resolver B
Resolver C

3 possible resolver identities
Now consider client prefixes:
With ECS:

198.51.100.0/24
198.51.101.0/24
198.51.102.0/24
198.51.103.0/24
...
The number of possible keys can become much larger.
RFC 7871 discusses how ECS affects caching and response scope because answers can vary according to network prefixes.
This does not mean ECS should be avoided.
It means implementations using ECS need to think about cardinality.
Suppose a metric records:
dns_queries_totalThat is one counter.
Easy.
Now add a label for destination:
dns_queries_total{destination="site-a"}
dns_queries_total{destination="site-b"}
dns_queries_total{destination="site-c"}
Still small.
Now add:
resolver_ipPotentially thousands of values.
Then:
client_prefixPotentially many more.
Then:
query_nameIf arbitrary names are accepted, the possible combinations multiply further.
Conceptually:
destination
    x
country
    x
ASN
    x
resolver
    x
prefix
    x
query name
The result can become huge.
This affects more than caches.
High-cardinality state can appear in:
Operators should ask:
Does this dimension really need its own retained entry?
Sometimes the correct answer is no.
A runtime table with 100,000 entries might sound manageable.
But entry count alone does not describe memory use.
Suppose each logical entry contains:
Prefix
ASN
Country
Timestamp
Policy identifier
Health metadata
Counters
Object overhead
Index metadata
The logical data may be small.
The actual in-memory representation can be much larger.
A useful planning model is:
Memory use =
entry count
x
average actual entry cost
+
indexes
+
allocator overhead
+
policy snapshots
+
temporary query memory
Exact memory accounting depends on the implementation language and data structures.
For capacity planning, operators need measurements from the real runtime.
The principle remains:
Traffic should not be able to cause memory use
to grow without a known ceiling.Memory is only half the issue.
Suppose a policy contains:
100,000 prefixesA new policy version arrives.
What happens?
Possible implementation A:
Pause query processing
     |
     v
Delete old table
     |
     v
Load 100,000 new entries
     |
     v
Build indexes
     |
     v
Resume queries
That could create a visible pause.
Another design might prepare the next policy version separately:
Current policy
      |
      | queries continue
      |
      +-------------------+
                          |
                    Build new policy
                          |
                          v
                     Validate
                          |
                          v
                     Ready?
                          |
                         yes
                          |
                          v
                    Switch snapshot
The details can vary greatly between implementations.
The important concept is that policy-update work should not unexpectedly block the query path.
A useful public design pattern is to treat routing policy as a versioned snapshot.
Conceptually:
Policy v41
   |
   | currently serving queries
   |
   +--------------------------+
                              |
                        Build Policy v42
                              |
                        Validate v42
                              |
                              v
                         Mark ready
                              |
                              v
                         Activate v42
After new queries use v42, the old snapshot can eventually be released when no longer needed.
This can help separate:
Policy preparationfrom:
DNS query processingBut snapshots need bounds too.
Bad:
v1
v2
v3
v4
v5
...
v500
all retained forever.
Better:
Active version
Previous version if needed
Version being prepared

Older versions discarded
Again, the exact implementation is not the point.
The principle is controlled lifetime.
Health state is an example where the natural limit can be tied to configured destinations.
Suppose:
Site A
192.0.2.10

Site B
198.51.100.10

Site C
203.0.113.10
A health table might contain:
Site A -> healthy
Site B -> healthy
Site C -> degraded
If only configured destinations can create health entries, the maximum size is naturally tied to configuration.
Maximum health records
=
Maximum configured destinations
That is easier to reason about than:
Create health state for every address observed at runtimeWhenever possible, bind state growth to operator-controlled configuration rather than arbitrary traffic.
Consider an authoritative service for:
api.example.comIt serves three destinations:
192.0.2.20
198.51.100.20
203.0.113.20
The steering system uses:
Health
Country
ASN
ECS when available
Prefix policy
Weighted fallback
Suppose its runtime state is designed like this:
| State | Limit | Lifetime |
|---|---|---|
| Active policy | 1 | Until replaced |
| Previous policy | 1 | Short transition period |
| Health entries | 3 | While destination exists |
| Resolver classifications | 25,000 | 30 minutes |
| Prefix classification cache | 50,000 | 15 minutes |
| Query context | Per active query | Query lifetime |
| Per-site counters | Fixed | Process lifetime |
The numbers are only examples.
But the structure gives operators answers to several important questions.
No.
Maximum = 25,000No.
Maximum = 50,000No.
Active = 1
Previous = 1No.
They are tied to configured destinations.
Ideally, not without a controlled reason.
This is the kind of predictability bounded state provides.
A bound is useful only if the system defines what happens at the boundary.
Suppose:
Resolver cache capacity:
25,000 entries
Entry 25,001 arrives.
Possible responses include:
Evict an older entry

Expire the least recently used entry

Do not cache the new result

Replace an entry selected by another fixed policy
Each has trade-offs.
What should not happen is:
Capacity = 25,000

Entry 25,001 arrives

Increase capacity automatically

Then 50,000

Then 100,000

Then 1,000,000
At that point the “limit” was not actually a limit.
Eviction sometimes sounds like failure.
It is not necessarily failure.
A cache exists to make repeated work cheaper.
The authoritative answer must not depend on every cached entry existing forever.
A useful pattern is:
Cache hit
    |
    v
Use cached information

Cache miss
    |
    v
Perform bounded lookup
    |
    v
Optionally cache result
If the cache is full:
Evict
or
Skip insertion
The query should still have a defined path.
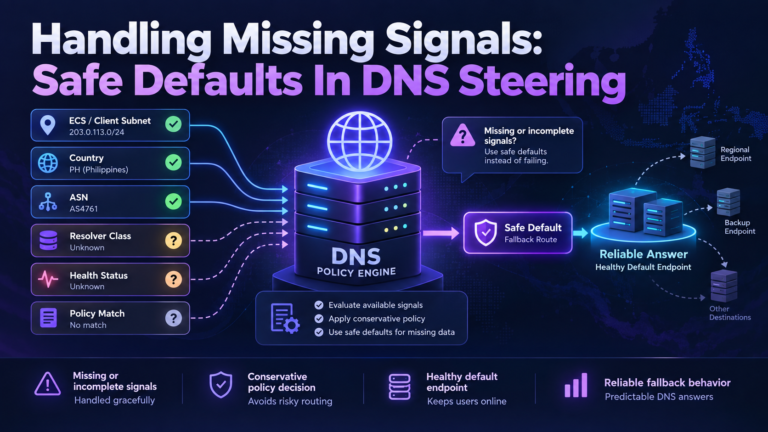
This is similar to the safe-default principle discussed in Article 12.
A missing cache entry should reduce convenience or increase bounded lookup work.
It should not make the DNS service unpredictable.
Systems sometimes remember failures.
For example:
Prefix lookup failed

Resolver classification unavailable

ASN unknown
Remembering this temporarily can prevent repeated expensive lookups.
But negative state must also expire.
RFC 2308 formalizes negative caching in DNS itself, including the caching of knowledge that a name or RRset does not exist.
A steering engine’s internal negative cache is a different implementation concern, but the broader engineering lesson is useful:
Negative information needs lifetime rules too.Otherwise a temporary lookup failure can become a long-lived incorrect assumption.
Suppose 100,000 cache entries all expire at exactly 12:00.
A naive cleanup process might do:
12:00:00

Delete entry 1
Delete entry 2
Delete entry 3
...
Delete entry 100,000
If all cleanup happens in one large operation, query latency can suffer.
This creates an important idea:
Bounding the amount of state is not enough. Maintenance work on that state should also have predictable cost.
Possible general approaches include:
Incremental expiration

Periodic small cleanup batches

Expiration during normal lookup

Time-bucketed expiration

Fixed maintenance budgets
Implementation choices vary.
The goal is to avoid a maintenance event whose cost suddenly scales with the entire runtime state.
Imagine 50,000 entries were created after a service restart.
All have:
TTL = 30 minutesAt approximately the same time:
50,000 entries expireThis can create:
Large cleanup work

Large classification refresh work

Large external lookup demand
This is sometimes called an expiration cliff or synchronized expiry problem.
Operators should test restart and recovery behavior, not just steady operation.
Suppose a DNS service restarts.
Ask:
What state disappears?

What state reloads?

What state rebuilds from traffic?

How quickly can it rebuild?

Can rebuilding overload another service?
Consider:
Restart
   |
   v
All classification caches empty
   |
   v
Traffic resumes
   |
   v
Every query becomes a cache miss
If every miss requires expensive external work, the restart can cause a large burst of activity.
A bounded design should consider cold-start behavior.
Possible approaches include:
Preload stable policy data

Keep external lookups bounded

Use safe defaults on lookup failure

Warm only essential state

Limit concurrent refresh operations
The system should remain able to answer DNS while optional state is rebuilding.
Suppose a query arrives.
The steering system needs ASN information.
A dangerous design might do this:
DNS query
    |
    v
External HTTP request
    |
    v
Wait
    |
    v
ASN result
    |
    v
DNS answer
Now authoritative DNS latency depends directly on another service.
If that external service slows down, DNS slows down.
A safer architecture usually keeps slow control or classification work away from the critical query path.
Conceptually:
Background/control process
        |
        v
Prepare classification data
        |
        v
Bounded local state
        |
        v
DNS query path
The exact design depends on the implementation.
The engineering objective is straightforward:
A normal DNS query should not trigger
unbounded waiting or unbounded external work.A useful mental model is:
             PREPARED STATE

       Policies
       Health
       Prefix maps
       Classifications
            |
            v

DNS Query
    |
    v
Read bounded state
    |
    v
Apply policy
    |
    v
Return answer
Compare that with:
DNS Query
    |
    +--> database query
    |
    +--> external API
    |
    +--> policy compilation
    |
    +--> health refresh
    |
    +--> cache cleanup
    |
    v
DNS Answer
The second architecture creates many opportunities for unpredictable latency.
Not every DNS system has to be completely free of runtime lookups.
But every dependency on the query path should have a known cost and failure behavior.
A system can have small state but still suffer if the state changes too frequently.
Imagine:
Policy size:
10 MB

Update rate:
once per second
If every update requires:
Parse 10 MB
Validate 10 MB
Build indexes
Allocate replacement objects
Discard previous state
the update rate may become more important than the memory size.
A complete bound therefore includes:
State size
+
Update frequency
+
Cost per update
A rough conceptual model is:
Runtime update work
=
update size
x
update frequency
This is not a precise performance formula.
It is a useful engineering question.
Suppose weighted DNS uses:
Site A = 60
Site B = 40
It might be tempting to continuously modify global counters or policy structures for every query.
Some counters are normal.
But operators should separate:
Read-mostly routing policyfrom:
Frequently changing telemetryIf the core policy structure needs heavy mutation for every query, concurrency and update cost become more complicated.
A simple model is often easier to reason about:
Policy
mostly read

Health
changes occasionally

Telemetry
updated separately

Query context
short lived
The exact internal implementation can vary.
The separation of concerns is what matters.
Observability is essential.
But observability systems can create their own state growth.
Suppose you expose:
dns_decisions_total{country="PH"}There are a limited number of country codes.
Fine.
Now expose:
dns_decisions_total{resolver_ip="x.x.x.x"}Potentially many values.
Then:
dns_decisions_total{
    resolver_ip="...",
    ecs_prefix="...",
    asn="...",
    qname="..."
}
The number of metric series can multiply rapidly.
A safer approach is often to aggregate around dimensions with controlled cardinality.
For example:
decision_reason
destination
policy_type
health_state
fallback_reason
Detailed troubleshooting information can go into sampled or rate-limited logs where appropriate.
Do not turn every runtime attribute into a permanent metric label.
Imagine receiving 100,000 unusual DNS queries per second.
If every query creates a large debug record:
100,000 queries/sec
x
1 KB log entry
=
~100 MB/sec
That is roughly:
~6 GB/minutebefore considering formatting and storage overhead.
A logging system can become the bottleneck instead of DNS.
Useful controls include:
Sampling

Rate limits

Aggregation

Debug mode with expiry

Per-event caps
Operators still need enough information to understand failures.
The goal is controlled visibility.
Avoid designs where every observed client or prefix creates permanent memory.
Internet inputs can have very high cardinality.
A cache without a maximum size is simply another growing data store.
Define:
Maximum entries
Expiration
Eviction behaviorA temporary classification failure should not become permanent truth.
Give negative state a lifetime.
Large policy changes should not unexpectedly stop DNS query processing.
Measure update behavior under realistic policy sizes.
Keeping old versions can help rollback.
Keeping every version in memory forever does not.
Bound the number of retained generations.
Deleting large numbers of expired entries at once can create latency spikes.
Control maintenance work.
Do not expose unbounded identifiers as metric labels without understanding the cost.
Resolver addresses, full query names, and client prefixes deserve particular care.
Logs consume CPU, memory buffers, network bandwidth, and storage.
Treat logging capacity as part of the system design.
Ask this question for every table:
Can an arbitrary Internet user cause a new entry to exist?
If the answer is yes, that table deserves strict limits.
A larger cache may increase hit rates.
It also consumes more memory and makes cleanup and restart behavior more important.
Cache size should solve a measured problem.
Create an inventory.
For example:
| State | Created By | Maximum Size | Lifetime |
|---|---|---|---|
| Policy snapshot | Configuration | Fixed | Until replaced |
| Health state | Configured endpoints | Fixed | Endpoint lifetime |
| Resolver cache | DNS traffic | Bounded | 30 minutes |
| Prefix cache | Network lookup | Bounded | 15 minutes |
| Query state | DNS query | Concurrency bound | Query lifetime |
| Metrics | Runtime events | Controlled labels | Process lifetime |
If a table cannot be explained, investigate it.
Any state influenced by arbitrary Internet traffic deserves a clear ceiling.
Examples:
Resolver cache
Client-prefix cache
Unknown-query tracking
Debug traces
Rate-limit tablesAsk:
When does this entry disappear?“Never” should require a strong reason.
Do not stop at:
Maximum = 50,000Also define:
What happens at 50,001?A query should not trigger:
Unlimited recursion through policy rules

Unlimited external lookups

Unlimited allocations

Full-table cleanup

Full-policy rebuilds
The query path should have a controlled amount of work.
Policy loading, classification refresh, bulk validation, and large data preparation are usually easier to control outside the critical answer path.
Prepare information before queries need it where practical.
Do not test only an empty cache.
Test:
Empty state

50% capacity

100% configured capacity

Rapid eviction

Large policy reload

Cold restart
Observe memory and query latency.
Ask what happens if:
Health changes repeatedly

Policy updates arrive rapidly

Classification entries expire together

Resolvers suddenly change behavior
A DNS system must handle changes as well as steady traffic.
Track:
Number of resolver entries
Number of prefix entries
Number of policy objects
Number of active metric series
Number of health records
Sudden growth can reveal a design problem or unusual traffic.
Limits should not exist only in developer assumptions.
Operators should know them.
Useful limits may include:
Maximum cache entries
Maximum policy size
Maximum retained versions
Maximum debug duration
Maximum log rate
Maximum classification lifetimeOn Linux, operators can watch the DNS process itself.
For example:
ps -o pid,rss,vsz,%mem,%cpu,cmd -p <PID>RSS gives a useful view of resident memory currently associated with the process.
You can also inspect process memory using:
grep -E 'VmRSS|VmSize|VmPeak' /proc/<PID>/statusFor a long-running DNS service, compare memory while:
Idle

Under normal traffic

Under high traffic

At cache capacity

During policy updates

After repeated updates

After traffic returns to normal
A particularly useful question is:
Does memory reach a plateau?If runtime memory continually increases with the number of unique queries, prefixes, or resolvers, investigate why.
A simplified architecture might look like this:
                 CONTROL SIDE

          Configuration Source
                 |
                 v
          Validate Policy
                 |
                 v
          Build Snapshot
                 |
                 v
       +-------------------+
       |   Active Policy   |
       +-------------------+

                 |
                 v

                  QUERY SIDE

DNS Query
    |
    v
Read active snapshot
    |
    v
Read bounded health state
    |
    v
Check bounded classification cache
    |
    v
Apply safe defaults if needed
    |
    v
Return DNS Answer
Supporting runtime state might look like:
+-----------------------------+
| Policy snapshots: fixed     |
| Health entries: fixed       |
| Resolver cache: bounded     |
| Prefix cache: bounded       |
| Metrics: bounded labels     |
| Query context: temporary    |
+-----------------------------+
This model gives operators something they can reason about.
A steering system can benefit from runtime information.
Health checks are state.
Caches are state.
Counters are state.
Policy generations are state.
The lesson is not:
Never keep state.The lesson is:
Keep only state whose size,
lifetime, purpose, and failure
behavior you understand.
State should earn its place in the authoritative query path.
A DNS steering service can influence:
Runtime state helps make these decisions.
Bounded state does not change the limits of DNS steering.
DNS cannot fully control:
RFC 8767 also allows recursive resolvers to serve stale cached DNS information in defined circumstances when fresh data cannot be obtained. This means authoritative policy changes do not always become visible to every client immediately.
HTTP behavior occurs at the application layer as defined by RFC 9110, while TCP maintains transport connection state according to RFC 9293. Changing an authoritative DNS decision does not directly move an existing TCP connection.
The steering engine should therefore focus on what it can control well:
Fast answer generation
Predictable memory
Predictable policy evaluation
Controlled state
Safe fallback behaviorToday’s traffic does not define tomorrow’s maximum cardinality.
Ask what happens under the largest expected state.
How?
When?
How much work will cleanup require?
If those questions do not have answers, cleanup is not designed yet.
Increasing the limit moves the boundary.
It does not remove the need for one.
Most runtime classifications do not need permanent lifetime.
Expire or aggregate information where appropriate.
ECS can provide useful network context.
It also increases the number of possible network-specific inputs. RFC 7871 explicitly deals with network scope and caching considerations for tailored DNS answers.
Use the signal without allowing uncontrolled state growth.
They can if the update consumes the same CPU, memory, locks, or execution path used by query handling.
Test policy updates while traffic is active.
They do.
High-cardinality metrics can consume substantial memory in the application and monitoring system.
At DNS traffic volumes, unrestricted per-query logs can generate large I/O loads.
Rate-limit or sample where appropriate.
Unknown ASN, country, or resolver classification may reflect a temporary lookup problem.
Temporary uncertainty needs an expiration.
No.
A bounded table can still be expensive if every query scans all entries.
You need bounds on:
State size
and
work performed against that stateDNS steering runtime state should be controlled in four main dimensions:
SIZE
How much state can exist?

SCOPE
What can create unique state?

LIFETIME
How long can it remain?

UPDATE COST
How much work does changing it require?
A useful summary is:
              BOUNDED STATE

        +------------------+
        | Maximum entries  |
        +------------------+
                 |
        +------------------+
        | Maximum lifetime |
        +------------------+
                 |
        +------------------+
        | Controlled keys  |
        +------------------+
                 |
        +------------------+
        | Bounded updates  |
        +------------------+
                 |
                 v
       Predictable DNS runtime
Important rules include:
Do not let Internet traffic create unlimited permanent state.
Set maximum sizes for runtime caches.
Expire temporary information.
Define eviction behavior before capacity is reached.
Keep policy updates from unexpectedly blocking query handling.
Watch ECS and resolver-related cardinality.
Treat metrics and logs as part of runtime resource use.
Test cold starts, cache saturation, cleanup, and rapid policy changes.
Bind state to operator-controlled configuration whenever practical.
Keep per-query work predictable.
A DNS steering system does not need to be stateless.
It needs state whose behavior operators can understand before something goes wrong.
A steering system should remain understandable not only when it has ten rules and a small amount of traffic.
It should remain predictable when policies grow, signals change, caches fill, health updates arrive, and Internet traffic behaves differently from what operators expected.
That is why bounded runtime state is a core part of production DNS engineering.