Physical Address
Metro Manila, Philippines
Physical Address
Metro Manila, Philippines
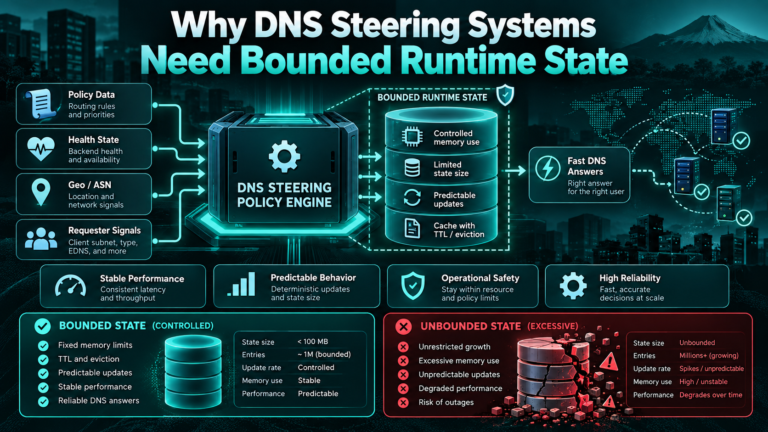
DNS steering often looks simple when every signal is available.
A query arrives. The system knows the client network. It identifies the country and ASN. Health checks are current. A matching policy exists. The DNS server returns the intended destination.
Production networks are rarely that tidy.
Sometimes EDNS Client Subnet, or ECS, is missing. An IP-to-country database may not recognize a prefix. An ASN lookup can fail. A recursive resolver may not be classified. Health information may be old or unavailable. A query may simply match no special routing policy.
A DNS steering system must still decide what to do.
This is where safe defaults matter.
A good default does not try to guess missing information. It provides predictable behavior when the preferred decision cannot be made.
The basic principle is:
Missing information should reduce steering precision, not automatically cause an outage.
That sounds simple, but applying it correctly requires operators to distinguish several very different kinds of “unknown.”
Consider www.example.com.
Three service locations are available:
Site A
192.0.2.10

Site B
198.51.100.10

Site C
203.0.113.10
The DNS steering policy might normally use several signals:
DNS Query
    |
    v
ECS available?
    |
    v
Country
    |
    v
ASN
    |
    v
Resolver classification
    |
    v
Policy match
    |
    v
Health status
    |
    v
DNS Answer
When everything works, the decision might be straightforward.
For example:
Country = PH
ASN = AS-Example-A
Health = healthy

Result:
192.0.2.10
But what happens when the request looks like this?
ECS = missing
Country = unknown
ASN = unknown
Resolver class = unknown
Health = available
Policy match = none
The DNS service still needs a response.
A fragile design may respond unpredictably, return an inappropriate destination, or even generate an error.
A safer design deliberately defines what happens at every missing-data boundary.
The first rule of safe fallback design is simple:
UNKNOWN != FALSE
UNKNOWN != HEALTHY
UNKNOWN != UNHEALTHY
Suppose a database lookup normally returns:
Country = PHIf the lookup fails, that does not mean:
Country != PHIt means:
Country = unknownThe difference matters.
The same applies to ASN information:
Known:
ASN = AS64500

Missing:
ASN = unknown
Do not turn missing information into an invented value.
The steering system should explicitly recognize unknown states.
One practical way to design defaults is to move from specific information toward broader policies.
Conceptually:
Most specific
     |
     v
Prefix policy
     |
     v
ASN policy
     |
     v
Country / region policy
     |
     v
Resolver-based policy
     |
     v
General weighted policy
     |
     v
Stable default
This is not a DNS protocol requirement.
It is an operational design pattern.
If a specific signal is unavailable, the system can continue using information that is still available.
For example:
ECS available
    |
    +--> Prefix match
    |
    +--> ASN match
    |
    +--> Country match
Without ECS:
ECS missing
    |
    v
Do not pretend the client prefix is known
    |
    v
Use other trusted context
    |
    v
General policy
The important point is that losing one signal should not automatically destroy the entire decision process.
EDNS Client Subnet allows a recursive resolver to provide part of a client’s network prefix to an authoritative DNS service.
RFC 7871 defines this mechanism and also discusses its caching, privacy, and operational implications.
ECS is useful for network-sensitive DNS decisions.
It should not be treated as mandatory.
A normal query path may look like:
Client
   |
   v
Recursive Resolver
   |
   | ECS available
   v
Authoritative DNS
   |
   v
Client-prefix-aware policy
But many queries can look like this:
Client
   |
   v
Recursive Resolver
   |
   | No ECS
   v
Authoritative DNS
In this case, the authoritative server usually knows the recursive resolver’s address, not the actual end user’s address.
The DNS architecture has always included recursive resolvers and caching between clients and authoritative servers. RFC 1034 describes this resolver and authoritative-server model.
When ECS is missing:
Do not invent client-prefix information.Instead, move to a policy that does not require ECS.
For example:
ECS?
 |
 +-- yes --> client-prefix-aware policies
 |
 +-- no ---> general resolver/default policy
A possible fallback might be:
No ECS
    |
    v
All healthy destinations
    |
    v
Weighted default
    |
    v
192.0.2.10 or 198.51.100.10
This sacrifices some steering precision.
That is usually better than pretending that the authoritative server has information it does not actually possess.
Sometimes.
But operators must understand what that means.
Suppose:
User
198.51.100.x
       |
       v
Public Recursive Resolver
203.0.113.x
       |
       v
Authoritative DNS
Without ECS, a geographic or ASN lookup may classify:
203.0.113.xThat describes the resolver infrastructure.
It does not necessarily describe:
198.51.100.xwhich represents the user network.
Resolver-based classification can still be useful as a fallback if you understand its limitations.
It should be treated as:
Resolver contextrather than:
Confirmed client contextSuppose a steering policy contains:
Country PH -> Site A
Country SG -> Site B
Country US -> Site C
A query arrives, but the location database returns:
Country = unknownWhat should happen?
A dangerous approach would be:
Unknown country -> randomly guess a countryAnother bad approach would be:
Unknown country -> refuse DNS resolutionNeither is necessary.
Use a broader policy.
For example:
Country lookup
     |
     +-- PH --> Site A
     |
     +-- SG --> Site B
     |
     +-- US --> Site C
     |
     +-- unknown --> General pool
The general pool might contain:
192.0.2.10
198.51.100.10
203.0.113.10
or only the locations that operators consider suitable as global defaults.
The default should be an explicit configuration decision.
It should not be an accidental result of missing data.
ASN-aware steering is useful when an operator knows that particular networks perform better through particular infrastructure.
For example:
ASN A -> Site A
ASN B -> Site B
ASN C -> Site C
But ASN information may not always be available.
The lookup source might not recognize the address.
Routing information may have changed.
The address might not map cleanly to the expected dataset.
Or ECS may be absent, leaving only resolver context.
Treat missing ASN information as:
ASN = unknownThen continue with a less specific rule.
For example:
Prefix match?
    |
    no
    |
    v
ASN known?
    |
    +-- yes --> ASN policy
    |
    +-- no ---> Geographic policy
                       |
                       v
                    Default
The system should not assume that an unknown ASN belongs to the most common network.
That creates hidden routing bias.
Operators may classify known recursive resolvers.
For example:
Known ISP resolver
Public resolver
Enterprise resolver
Unknown resolver
That information can help the system decide how much confidence to place in resolver-based geography or network ownership.
But new resolvers appear.
Resolver addresses change.
A query may arrive from infrastructure that has never been classified.
The safe response is not:
Unknown resolver -> blockunless there is a separate security reason to do so.
For DNS steering, an unknown resolver should usually fall back to a general policy.
Known resolver
     |
     v
Resolver-specific policy

Unknown resolver
     |
     v
General policy
Unknown classification means the routing system has less context.
It does not necessarily mean the DNS request is invalid.
This is one of the easiest failure modes to prevent.
Suppose the rules are:
198.51.100.0/24 -> Site A
203.0.113.0/24  -> Site B
ASN A           -> Site A
Country PH      -> Site C
A query arrives that matches none of them.
What happens?
A good steering configuration should have an explicit final rule.
Specific policies
      |
      v
No match
      |
      v
DEFAULT
For example:
Default:
  Site A weight 50
  Site B weight 50
or:
Default:
  Site A
The exact policy depends on the service.
What matters is that no policy match is itself an expected condition.
It should have defined behavior.
Operators sometimes focus heavily on special routing rules.
They configure:
Country rules
ASN rules
Prefix rules
Failover rules
and treat the default as an afterthought.
That is backwards.
A large percentage of unexpected requests may eventually reach the default.
The default path should therefore be designed deliberately.
A strong default generally has these properties:
Known
Predictable
Reachable
Capacity-aware
Observable
Simple
The default should also avoid depending on the same optional signal that caused the fallback.
For example, this is not useful:
ASN missing
    |
    v
Fallback to another ASN-dependent rule
The fallback must remove the failed dependency.
Health information requires special handling.
Consider three states:
HEALTHY
UNHEALTHY
UNKNOWN
They do not mean the same thing.
The monitoring system has sufficiently recent evidence that the endpoint is operating within the defined health criteria.
The monitoring system has evidence that the endpoint should not currently receive new DNS-directed traffic.
The monitoring system cannot confidently determine the endpoint’s current state.
That may happen because:
The dangerous mistake is collapsing these states.
Suppose:
Site A = healthy
Site B = health unknown
Treating Site B as definitely healthy would ignore uncertainty.
But treating every unknown endpoint as immediately down creates another problem.
Imagine a temporary monitoring outage:
Site A = unknown
Site B = unknown
Site C = unknown
If the DNS system immediately removes every endpoint, the monitoring failure may turn into a service outage even though all three application sites are still working.
This is why health fallback policy needs more care than country or ASN fallback.
A conceptual health process might look like this:
Fresh health information available?
          |
       +--+--+
       |     |
      yes    no
       |     |
       v     v
   Use state  Health unknown
                  |
                  v
          Apply bounded fallback
Possible bounded fallback approaches include:
The exact choice depends on the service and its failure tolerance.
The key principle is:
Do not let temporary loss of monitoring automatically become loss of DNS service.
At the same time:
Do not trust stale health information forever.
Those two requirements must be balanced.
Suppose Site A was healthy at 10:00.
At 10:01, the health monitoring system becomes unavailable.
A steering system might temporarily continue treating Site A according to its recent state.
Conceptually:
10:00
Site A = HEALTHY

10:01
Health data unavailable

10:02
Use recent known state

10:??
Recent state exceeds allowed age
      |
      v
Apply unknown-health policy
This prevents a short monitoring interruption from causing immediate steering changes.
However, an old health result eventually becomes unreliable.
A safe implementation needs a defined freshness boundary.
The exact number depends on the application, health-check interval, incident tolerance, and infrastructure design.
Do not confuse internal stale health information with DNS resolvers serving stale DNS records.
They are different mechanisms.
RFC 8767 describes how recursive resolvers can sometimes serve expired cached DNS data when refreshing the record fails.
That means an operator may change an authoritative DNS answer while some recursive resolvers can still temporarily return older information under specific failure conditions.
This reinforces an important lesson:
Authoritative policy change
        !=
Instant global traffic change
DNS steering influences future resolution behavior.
It does not directly erase resolver caches or terminate existing connections.
This is one of the hardest default-policy questions.
Suppose:
Site A = unhealthy
Site B = unhealthy
Site C = unhealthy
There is no universal answer.
Two broad approaches exist.
Return one or more destinations even though health checks indicate problems.
The reasoning is that a degraded service may still be better than no answer.
Possible risk:
DNS sends users toward infrastructure known to be failing.Stop returning normal service endpoints.
Possible outcomes could include an alternate emergency service or, depending on the DNS design, a server failure response.
Possible risk:
Users receive no usable destination even if the health system was wrong.The correct choice depends on the application.
An informational website, financial transaction service, API, DNS infrastructure component, and emergency communications platform may require different behavior.
Operators should decide this before an incident.
If www.example.com exists, an unavailable application backend does not mean the domain name stopped existing.
Returning:
NXDOMAINcan therefore be semantically wrong.
It can also create additional operational problems because negative DNS answers can be cached.
RFC 2308 defines negative caching behavior for DNS responses such as NXDOMAIN and NODATA.
Consider:
Temporary backend problem
        |
        v
NXDOMAIN returned
        |
        v
Recursive resolver caches negative answer
        |
        v
Backend recovers
        |
        v
Some users may still see cached negative result
Failover logic should distinguish:
Name does not existfrom:
Service destination is unhealthyThese are different conditions.
Consider this public service:
www.example.comAvailable destinations:
Site A
192.0.2.10

Site B
198.51.100.10

Site C
203.0.113.10
The operator has the following conceptual routing goals:
Specific prefix -> preferred site
Specific ASN    -> preferred site
Country policy  -> regional site
General users   -> Site A or Site B
Unhealthy sites -> excluded where possible
A request arrives.
The steering system receives:
ECS: absent
Country: unknown
ASN: unknown
Resolver classification: unknown
Health:
  Site A = healthy
  Site B = healthy
  Site C = unhealthy
A safe decision path could be:
Query
 |
 v
ECS?
 |
 no
 |
 v
Skip ECS-dependent prefix policy
 |
 v
Trusted ASN available?
 |
 no
 |
 v
Country available?
 |
 no
 |
 v
Resolver-specific policy?
 |
 no
 |
 v
General default
 |
 v
Filter unhealthy destinations
 |
 v
Site A + Site B
 |
 v
Apply general distribution
 |
 v
Return DNS answer
The system did not need to guess.
It simply lost precision as information disappeared.
That is graceful degradation.
Now imagine:
ECS: present
Prefix: 198.51.100.0/24
Policy: prefer Site B

Health:
Site A = healthy
Site B = unknown
Site C = healthy
The prefix policy says:
198.51.100.0/24 -> Site BBut health confidence for Site B is missing.
A production design might choose one of several operator-defined behaviors:
Option A:
Use recent Site B state if still fresh.

Option B:
Skip Site B and use known-healthy fallback.

Option C:
Use an emergency general pool.

Option D:
Use Site B only if no known-healthy alternative exists.
There is no single DNS RFC that dictates which application-health policy is correct.
This is a service-design decision.
What matters is that the behavior is explicit, tested, observable, and documented.
A useful conceptual hierarchy might be:
                 DNS QUERY
                     |
                     v
             Determine context
                     |
                     v
              Health eligibility
                     |
                     v
               Prefix policy
                     |
               no usable match
                     |
                     v
                 ASN policy
                     |
               no usable match
                     |
                     v
              Country policy
                     |
               no usable match
                     |
                     v
             Resolver policy
                     |
               no usable match
                     |
                     v
             General policy
                     |
                     v
                  Default
This does not mean every implementation should use exactly this order.
The important requirement is that precedence is defined.
Operators should be able to answer:
What happens when a signal is missing?
and:
What happens when two policies could apply?
without reading source code or guessing.
Use dig to inspect the normal answer:
dig www.example.com AFor a compact result:
dig www.example.com A +shortYou can also directly query a documentation example authoritative server name during controlled testing:
dig @ns1.example.com www.example.com AWhere supported, dig can construct an ECS test query:
dig @ns1.example.com www.example.com A +subnet=198.51.100.0/24Compare that with a query that does not provide ECS.
The goal is to verify both paths:
ECS present
ECS absent
Do not test only the ideal case.
A DNS steering system should be tested against combinations of missing information.
For example:
| ECS | Country | ASN | Health | Expected Behavior |
|---|---|---|---|---|
| Present | Known | Known | Known | Specific policy |
| Missing | Known | Known | Known | Non-ECS policy |
| Missing | Unknown | Known | Known | ASN or broader policy |
| Missing | Unknown | Unknown | Known | General default |
| Present | Known | Known | Unknown | Health fallback policy |
| Missing | Unknown | Unknown | Unknown | Emergency/default behavior |
This table is often more useful operationally than testing only successful policy matches.
Production failures tend to occur at the edges.
Those edges need test cases.
Never convert:
unknowninto:
probably Xunless the system has a clearly documented source for that conclusion.
Uncertainty should remain visible.
A country database failure should not necessarily make DNS unavailable.
An ASN lookup failure should not necessarily make DNS unavailable.
Loss of ECS should not make DNS unavailable.
Use progressively broader policies.
Temporary fallback can be useful.
Permanent blind trust is dangerous.
Health information needs freshness limits.
The opposite extreme is also dangerous.
If every health check temporarily disappears, removing every endpoint can transform a monitoring problem into an application outage.
Every policy tree needs an end.
Bad:
Prefix?
  no

ASN?
  no

Country?
  no

???
Better:
Prefix?
  no
   |
ASN?
  no
   |
Country?
  no
   |
General defaultA default may receive traffic from:
That can be a significant amount of traffic.
The default infrastructure must be capable of handling its expected role.
If operators only see:
www.example.com -> 192.0.2.10they may not know why that destination was selected.
Operational logs or metrics should distinguish:
Prefix match
ASN match
Country match
General default
Missing ECS fallback
Unknown ASN fallback
Health fallback
No-policy fallback
The exact logging format is implementation-specific.
The principle is not.
Represent missing information directly.
Use:
country = unknownrather than inventing a country.
Use:
health = unknownrather than automatically converting uncertainty into healthy or unhealthy.
Before adding special routing policies, define:
What answer should a valid query receive when nothing special matches?If that question has no answer, the steering design is incomplete.
If ECS is missing, fall back to something that does not require ECS.
If ASN information is missing, use a rule that does not require ASN.
Fallback should reduce dependency.
Specific signal
      |
      v
Broader signal
      |
      v
General policyThese are different questions:
Who does this request represent?and:
Can this destination currently serve traffic?Country, ASN, prefix, and resolver classification describe request context.
Health describes destination eligibility.
Keeping these concepts separate makes policies easier to understand.
Ask explicitly:
What happens if the monitoring system disappears?Do not wait for an outage to decide.
Also ask:
What happens if every backend is marked unhealthy?Possible answers vary by service.
The important part is having an answer.
Recent information may be useful during short failures.
Old information eventually becomes unsafe.
Define how long last-known information remains trusted.
A domain that exists should not casually become NXDOMAIN because a backend health check failed.
Negative DNS responses have their own caching behavior. RFC 2308 documents this behavior.
Test more than:
Everything available
Everything healthy
Policy matches
Also test:
No ECS
Unknown country
Unknown ASN
Unknown resolver
No policy match
Missing health
All health unknown
All endpoints unhealthy
Those are production scenarios, not theoretical edge cases.
A fallback path that suddenly receives much more traffic can reveal a hidden problem.
For example:
Normal:
5% default fallback

Incident:
70% default fallback
That could indicate:
Fallback counters are therefore useful operational signals.
DNS steering can influence:
It can also provide safer behavior when optional routing signals disappear.
DNS cannot guarantee:
RFC 9110 defines HTTP as an application-level protocol with its own request and connection semantics.
TCP connection behavior is separately defined by RFC 9293. Changing a DNS answer does not rewrite an already established TCP connection.
DNS steering operates before many of these systems become involved.
That is why steering should be described as influence rather than complete traffic control.
No.
ECS is additional information carried through EDNS.
DNS must still work for ordinary requests that do not include ECS. RFC 6891 defines EDNS as an extension mechanism, while RFC 7871 defines the Client Subnet option carried through it.
You do not know that it is the closest country.
Use a defined broader policy instead.
That turns missing data into fabricated information.
Use the default policy.
A policy miss is usually an expected routing condition.
A final default should handle it.
Sometimes health is unknown because the monitoring system itself failed.
Treat unknown as its own state.
The opposite assumption is also unsafe.
Recent last-known information can be useful, but it must have a limit.
Resolvers cache DNS responses.
DNS was designed around distributed caching and timed refresh behavior. RFC 1034 describes caching as a core DNS design property.
Some resolvers can also serve stale cached data under conditions described by RFC 8767.
Existing connections may continue independently of DNS.
Safe defaults are a core part of DNS steering.
They are not emergency code paths that can be added later.
A useful mental model is:
Signal available?
      |
   +--+--+
   |     |
  yes    no
   |     |
   v     v
Specific  Broader
policy    policy
             |
             v
          Default
Remember these principles:
Missing ECS should reduce client-network visibility, not break DNS.
Missing country information should fall back to a broader routing policy.
Missing ASN information should remain unknown rather than being guessed.
Unknown resolver classification should normally use a general policy.
No policy match should reach an explicit default.
Unknown health should be different from healthy and unhealthy.
Last-known health information can be useful temporarily, but should not remain trusted forever.
NXDOMAIN should not be used casually to represent an unhealthy backend.
Fallback usage should be observable so operators know when steering precision has degraded.
The goal is predictable degradation:
Full information
      |
      v
Precise steering
      |
Signal lost
      |
      v
Broader steering
      |
More signals lost
      |
      v
Safe default
Not:
Signal lost
      |
      v
Guess
      |
      v
Unexpected outage
A mature DNS steering design knows what to do when information is incomplete.
Because eventually, information will be incomplete.
Real systems must handle degraded monitoring, incomplete network information, policy gaps, caching, failures, recovery, and unexpected request patterns.
The best steering policy is not only the one that makes the correct decision when every input is available.
It is also the one that behaves predictably when some inputs disappear.
Real systems must handle degraded monitoring, incomplete network information, policy gaps, caching, failures, recovery, and unexpected request patterns.
The best steering policy is not only the one that makes the correct decision when every input is available.
It is also the one that behaves predictably when some inputs disappear.